Robots.txt Generator
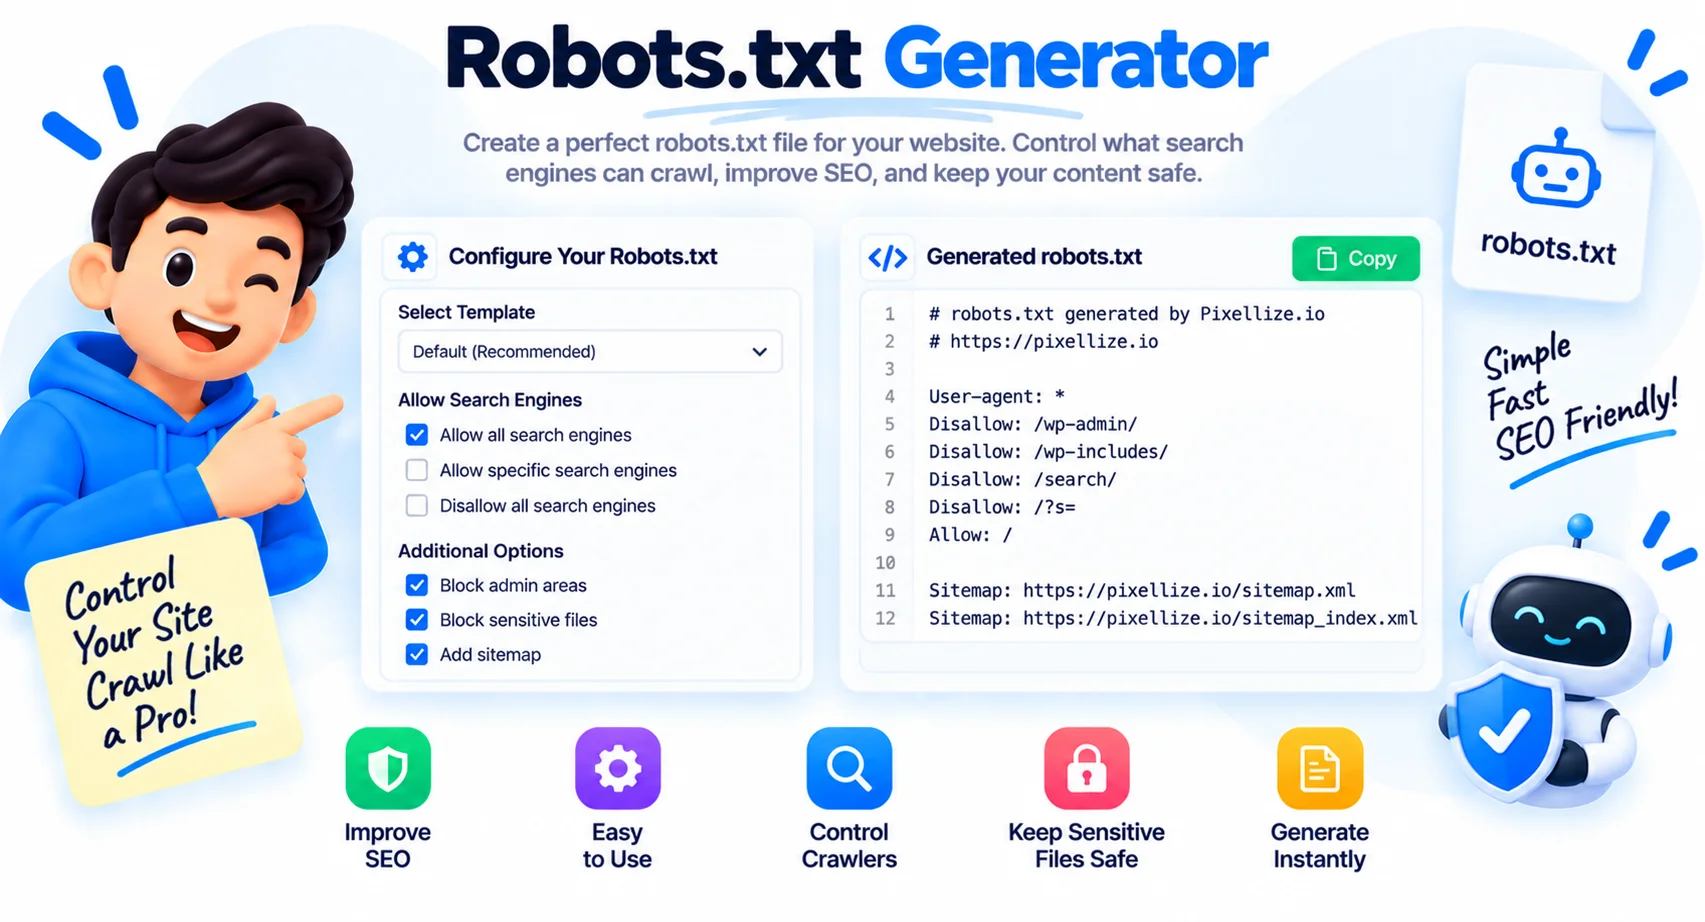
A free robots.txt generator. Set crawler rules, block AI bots like GPTBot and ClaudeBot with one click, add your sitemap, and copy or download a valid robots.txt file. No signup, everything runs in your browser.
How to use the robots.txt generator
Pick a Starting Point
Use a quick-start preset like Allow everything, Block everything, or WordPress, or build your own rules from scratch.
Set Your Rules
Add a user-agent, list the paths to disallow or allow, check any AI crawlers to block, and paste your sitemap URLs. The file updates as you type.
Copy or Download
Copy the robots.txt or download the file, then upload it to the root of your site so it loads at yoursite.com/robots.txt.
Create a robots.txt File, the Right Way
Every crawler looks for a robots.txt file before it visits your pages. That small text file at the root of your site tells search engines and bots which parts to crawl and which to skip, from admin folders to thin or private pages you do not want spending crawl budget. Writing it by hand is easy to get wrong, and one stray slash can block your whole site. This robots.txt generator builds a valid file for you, with a live preview so you see exactly what each rule does.
Robots.txt syntax, in plain English
A robots.txt file is a set of rule groups. Each group names a crawler and lists what it can and cannot fetch:
- User-agent is the crawler the rule applies to. Use
*for all bots, or a name likeGooglebot. - Disallow is a path the crawler should not fetch, such as
/wp-admin/. - Allow re-opens a path inside a disallowed folder, like
/wp-admin/admin-ajax.php. - Sitemap points crawlers to your sitemap URL so they find your pages faster.
Common robots.txt mistakes to avoid
A single line can break crawling, so watch for these:
- Disallow: / blocks your entire site. Use it only on staging, never in production.
- Blocking CSS or JavaScript stops Google from rendering the page the way visitors see it, which can hurt rankings.
- Wrong case. Paths are case-sensitive, so
/Blog/and/blog/are different. - Treating it as security. robots.txt is a request, not a lock. Do not rely on it to hide sensitive URLs.
Block AI crawlers
Modern sites also decide whether AI crawlers can train on their content. One click here adds a Disallow-all rule for the major AI bots, including GPTBot, ChatGPT-User, ClaudeBot, Google-Extended, PerplexityBot, CCBot, and Bytespider, so you can keep your pages out of AI training and answer engines if you choose.
Where to put robots.txt and how to test it
Save the file as robots.txt and upload it to the root of your domain, so it loads at yoursite.com/robots.txt. A site can have only one. After it is live, paste a URL into Google Search Console’s robots.txt report to confirm the right pages are allowed and blocked.
Why Use This Robots.txt Generator
Quick-Start Presets
One click for Allow everything, Block everything, or a sensible WordPress setup. Tweak from there.
Block AI Crawlers
Tick a box to keep GPTBot, ClaudeBot, CCBot, Google-Extended, and other AI bots out of your content.
Multiple Rule Groups
Set different Allow and Disallow rules for each user-agent, with as many groups as you need.
Crawl-delay Support
Add a crawl-delay for bots that respect it, to ease load on busy servers.
Sitemap Lines
List one or more sitemap URLs and they are added to the file in the right format.
Live Preview
See the finished robots.txt update as you type, then copy or download it in one click.
Similar Tools
More SEO tools you might find useful.
Frequently Asked Questions
Common questions about robots.txt and crawler control.
How do I create a robots.txt file?
Pick a starting preset, set your crawler rules, optionally block AI bots and add your sitemap, then copy or download the file. Save it as robots.txt and upload it to the root of your domain so it loads at yoursite.com/robots.txt. This generator writes valid syntax for you, free.
What is a robots.txt file?
A robots.txt file is a plain text file at the root of your site that tells crawlers which pages or folders they may or may not fetch. Search engines read it before crawling, so it helps you steer crawl budget and keep low-value pages out of the queue.
Where do I put the robots.txt file?
At the root of your domain, so it is reachable at yoursite.com/robots.txt. It will not work in a subfolder, and a site can have only one robots.txt file.
Does robots.txt stop a page from being indexed?
Not reliably. Disallow stops crawling, but a blocked URL can still appear in search if other pages link to it. To keep a page out of the index, use a noindex meta tag or header instead, and leave it crawlable so Google can see the noindex.
Can I block AI crawlers with robots.txt?
Yes. Click Block AI crawlers to add Disallow rules for bots like GPTBot, ClaudeBot, Google-Extended, and PerplexityBot. Compliant AI crawlers honor these rules, though robots.txt is a request, not enforcement.
What does Disallow: / do?
It blocks the entire site for that user-agent. It is useful on a staging server, but on a live site it will remove you from search, so use it with care.
What does an empty Disallow mean?
An empty Disallow (Disallow: with nothing after it) means allow everything. It is the standard way to say a crawler may access the whole site.
Is this robots.txt generator free?
Yes, it is completely free with no sign-up and no limits. Everything runs in your browser, so nothing is uploaded.